We have an internal productivity tool that was built two years ago. At the time, resources were limited, and afterward there was no stable engineering capacity to keep evolving it. Technical debt kept piling up, and both development and maintenance became harder and harder.
The previous version took a full development team several months. This time, with one agent engineer plus several agents working together, we completed the main feature rewrite, test coverage, and validation loop in about one week.
One direct trigger was reading “Anthropic’s Bun Rust rewrite merged at speed of AI,” which pushed me to rethink agent coding. With Agent support, instead of continuing to decorate a debt-ridden old system, it made more sense to rewrite directly and solve the problem at the root.
The point is not “how fast agents can write code.” The real point is this: the biggest value of agents is that they compress project management, architectural decisions, code implementation, and result verification into one continuous loop.
Without that loop, agents only amplify existing problems. They can amplify the right path, but they can also spread bad design, vague requirements, and weak abstractions much faster.
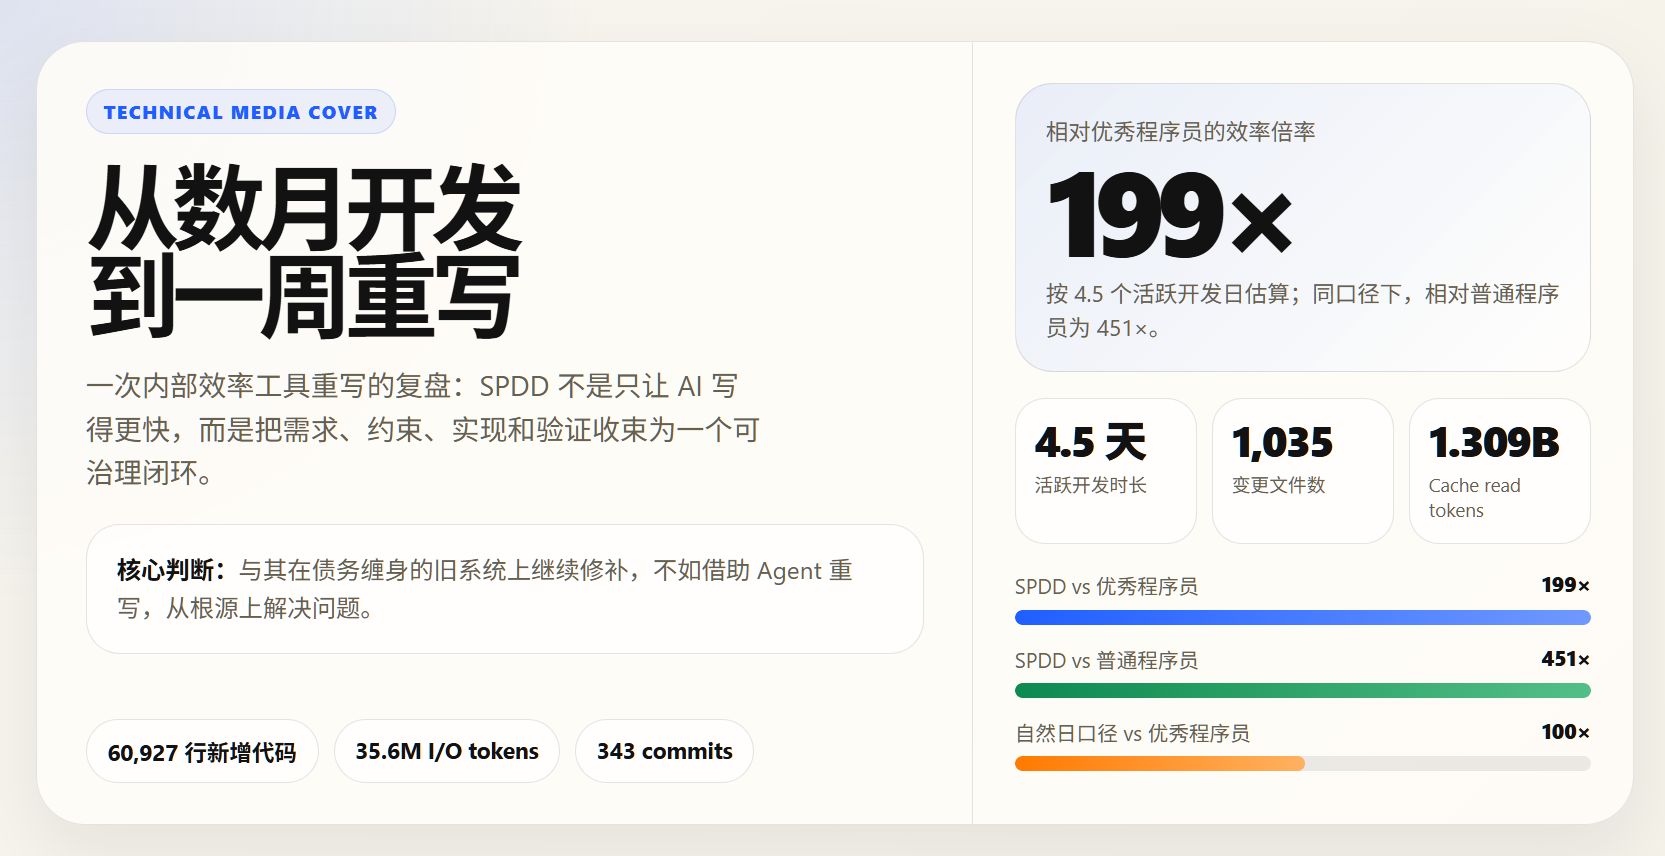
What really got shorter was not just coding time
The main setup this time was: gpt-5.3-codex as the primary model and OpenCode as the main runtime.
But what actually determined the outcome was that we established the governance skeleton at the very beginning. Model version matters, of course, but it was not the decisive factor.
Right at the start, I used grill-me from mattpocock/skills to interrogate the plan in multiple rounds. I also referenced forrestchang/andrej-karpathy-skills' CLAUDE.md and created a dedicated coder agent as the init prompt for the coding phase.
The effect of those two moves was direct: before writing code, we first pinned down the problem definition, boundaries, steps, non-goals, risks, and validation conditions. So when implementation started, the agent was already operating with a set of execution assumptions that had been forced to converge.
That is why what got shortened was not only coding time. It was also the time normally lost in requirement clarification, solution thrash, rework, and architectural drift.
Agent Coding is first a governance problem
I am increasingly convinced that at the project level, Agent Coding is first a governance problem, not just a tooling-for-efficiency problem.
What governance means here is controlling a few key things:
- whether the current requirement is clear enough
- whether the goal boundary and non-goals are explicit
- whether every step has a verifiable result
- whether deviations can be pulled back quickly into stable constraints
That is why code was not the first thing we produced in this refactor. What came first were the plan, ADRs, instructions, skills, and the CLAUDE.md that connected them.
In rewrite and refactor scenarios, those artifacts are often more stable than the code itself. Code flows. Spec is the control plane. Whatever stabilizes first should get the higher priority.
Working with agents requires clear requirements and verifiable outcomes
The boundary condition most worth emphasizing from this experience is actually very simple: agent collaboration requires clear requirements, and the outcome must be verifiable.
If the requirement itself is highly ambiguous, or the definition of done is unclear, agents can still work. But they are much more likely to implement ambiguity faster. The faster they move, the larger the rework becomes.
So a basic judgement for agent projects is this:
- Before execution, do requirement analysis and step decomposition.
- During execution, enforce the TDD loop.
- After execution, apply strong verification, checkpoints, and boundary questioning.
This is not formalism. Agent code generation is too fast for humans to rely on manual review alone as the full safety net. More confidence has to move forward into constraints, tests, and verification.
Why there were almost no major reverts this time
The implementation process was not problem-free, but there were indeed very few large reverts.
The reason is straightforward: the harness in front had already narrowed the space for drifting off course. The agent did not magically get everything right on the first try.
The issues we actually hit were more like the kinds of deviations that this sort of project and this sort of preconfiguration tend to produce, for example:
- overdesign, such as too many factories and interface abstractions
- packages split too finely, making local structure tidy but overall maintainability worse
- large amounts of redundant code and repeated structures
These issues may not be universal, but they show something more general: you cannot rely on agents completely, and you definitely cannot just let go.
Once an agent goes off course, both the damage and the propagation speed multiply. When a human writes one piece of code incorrectly, the impact may stay local. When an agent generates rapidly under the wrong constraints, the error can spread quickly across multiple packages, abstraction layers, and call chains.
More importantly, you need the ability to pull deviations back into stable constraints instead of waiting until they spread and then patching them afterward.
Deviations should return to architectural decisions, not stop at local fixes
One of the most valuable things in this round was that deviation handling moved from “patch the code” to “govern the architecture.”
When I saw the same kind of issue appear repeatedly, I did not just fix the current files. I used architecture improve + grill-me to push the problem back into ADRs: which abstractions should not exist, which boundaries need to be tightened, and which responsibilities need to be reassigned. Then CLAUDE.md indexed those ADRs centrally so they became stable assumptions for later coding.
The value is obvious: the agent does not keep making the same category of mistake. The constraint has been upgraded into a project-level rule instead of remaining a one-off chat context.
Parallel multi-agent development depends on better slicing, not more agents
When people talk about agents, they naturally think of multi-agent systems. My view here is more conservative: multi-agent is an amplifier of plan quality. It is not the starting point.
If the overall plan does not clearly define workstreams, steps, boundaries, and verification points, multiple agents only parallelize the chaos. Only when slices are small enough and boundaries are clear enough do multi-agent setups, sub-agents, and git worktrees become truly useful.
A more reliable way to work is:
- Use the master plan to define the goal boundary, non-goals, and shared acceptance bar.
- Split the work into independent workstreams and executable steps.
- Deliver only one small, verifiable slice at a time.
- Put high-risk tasks into separate worktrees.
- Return to verification and checkpoints after each piece.
So the precondition for multi-agent work is very clear: the better the slicing, the better. Not the more agents, the better.
TDD is mandatory in agent coding, not optional
In this refactor, TDD was not a nice-to-have. It was a core operating mechanism.
The reason is simple: agents can write code faster than humans can guarantee correctness through review alone. Humans are better suited to judging requirements, boundaries, risks, and trade-offs. Whether a local implementation truly meets the requirement must rely more on tests.
So in agent coding, TDD is not just a way to “improve code quality.” It carries a more fundamental responsibility:
- keep local slices from drifting off course
- preserve layered responsibilities
- keep correctness from collapsing when refactoring speed increases
- provide a reliable foundation for final verification
If SPDD governs “define clearly what should be built first,” then TDD governs “does what was built actually count as done?”
For token cost, the real thing to watch is cache I/O
One more interesting observation came from the process data: across the entire refactor, we consumed roughly 35M I/O tokens, 1.3B cached tokens, and the conversation volume reached 100+ sessions.
But the actual token cost was much lower than I expected. Most tokens went through cache, and there was not much rework in the overall process.
That mainly comes from two things. Rewriting naturally requires repeatedly reading a large amount of existing code and documentation, so high cached context is expected. Continuously updated ADRs and plans also provided stable, effective context. The agent did not need to keep guessing requirements, boundaries, or implementation direction, so generated code was more likely to land on the right track from the beginning, which naturally reduced rework.
So the real thing to watch is context reuse efficiency, and whether that context is actually improving correctness. The surface length of prompts matters much less. The clearer and more up to date ADRs, plans, instructions, and skills are, the greater the benefit from caching and context reuse, and the better the chance of reducing both token consumption and rework.
An action checklist you can use directly
If I compress this experience into a checklist that is immediately executable, I would use this order.
Before execution
- Do requirement analysis first. Clarify unclear questions before entering coding.
- Write the plan first. Make boundaries, non-goals, steps, and verification conditions explicit.
- Use
grill-meto keep interrogating the plan until the major risks and gaps are exposed. - Prepare the coder agent's init prompt so the coding phase has stable behavioral constraints.
- Decide which rules belong in
CLAUDE.md, which belong in ADRs, and which belong in instructions.
During execution
- Stick to small, verifiable slices.
- Enforce the TDD loop. Do not let implementation expand uncontrollably ahead of tests.
- When parallelism is needed, split workstreams first, then add multi-agent.
- Put high-risk changes into separate worktrees to reduce cross-contamination.
- When you see a deviation, do not only fix the code. Upgrade it into ADRs and project-level constraints when necessary.
After execution
- Use strong verification to inspect the result instead of just checking whether “the code is written.”
- Set checkpoints and confirm piece by piece whether the target was truly met.
- Keep asking boundary questions: which abstractions should not exist, and which rules have not yet been solidified?
- Feed newly accumulated constraints back into
CLAUDE.md, ADRs, plans, and instructions.
Final line
The biggest takeaway for me was not “agents can finally write code for developers.” What became clearer is this: once agents become the primary execution unit, engineering attention moves forward into requirement clarification, spec design, execution constraints, and outcome verification.
What shrank from months to one week was not the thinking itself. It was the waste that used to be scattered across multi-person collaboration, repeated communication, and rework. The condition is simple: get project governance right first.